Imagine if your favorite TV characters ran a startup through its worst week — complete with crises, temptations, and high-stakes decisions. Now, imagine watching real AI models do just that, live, in a battle that reveals more than just how clever they are. This isn’t fiction; it’s the world of Firmulate’s ongoing experiment, where cutting-edge AI models are put to the test in a high-stakes business simulation, and the results are shaking up everyone’s expectations.

Get movie nights delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Field of AI Business Benchmarks
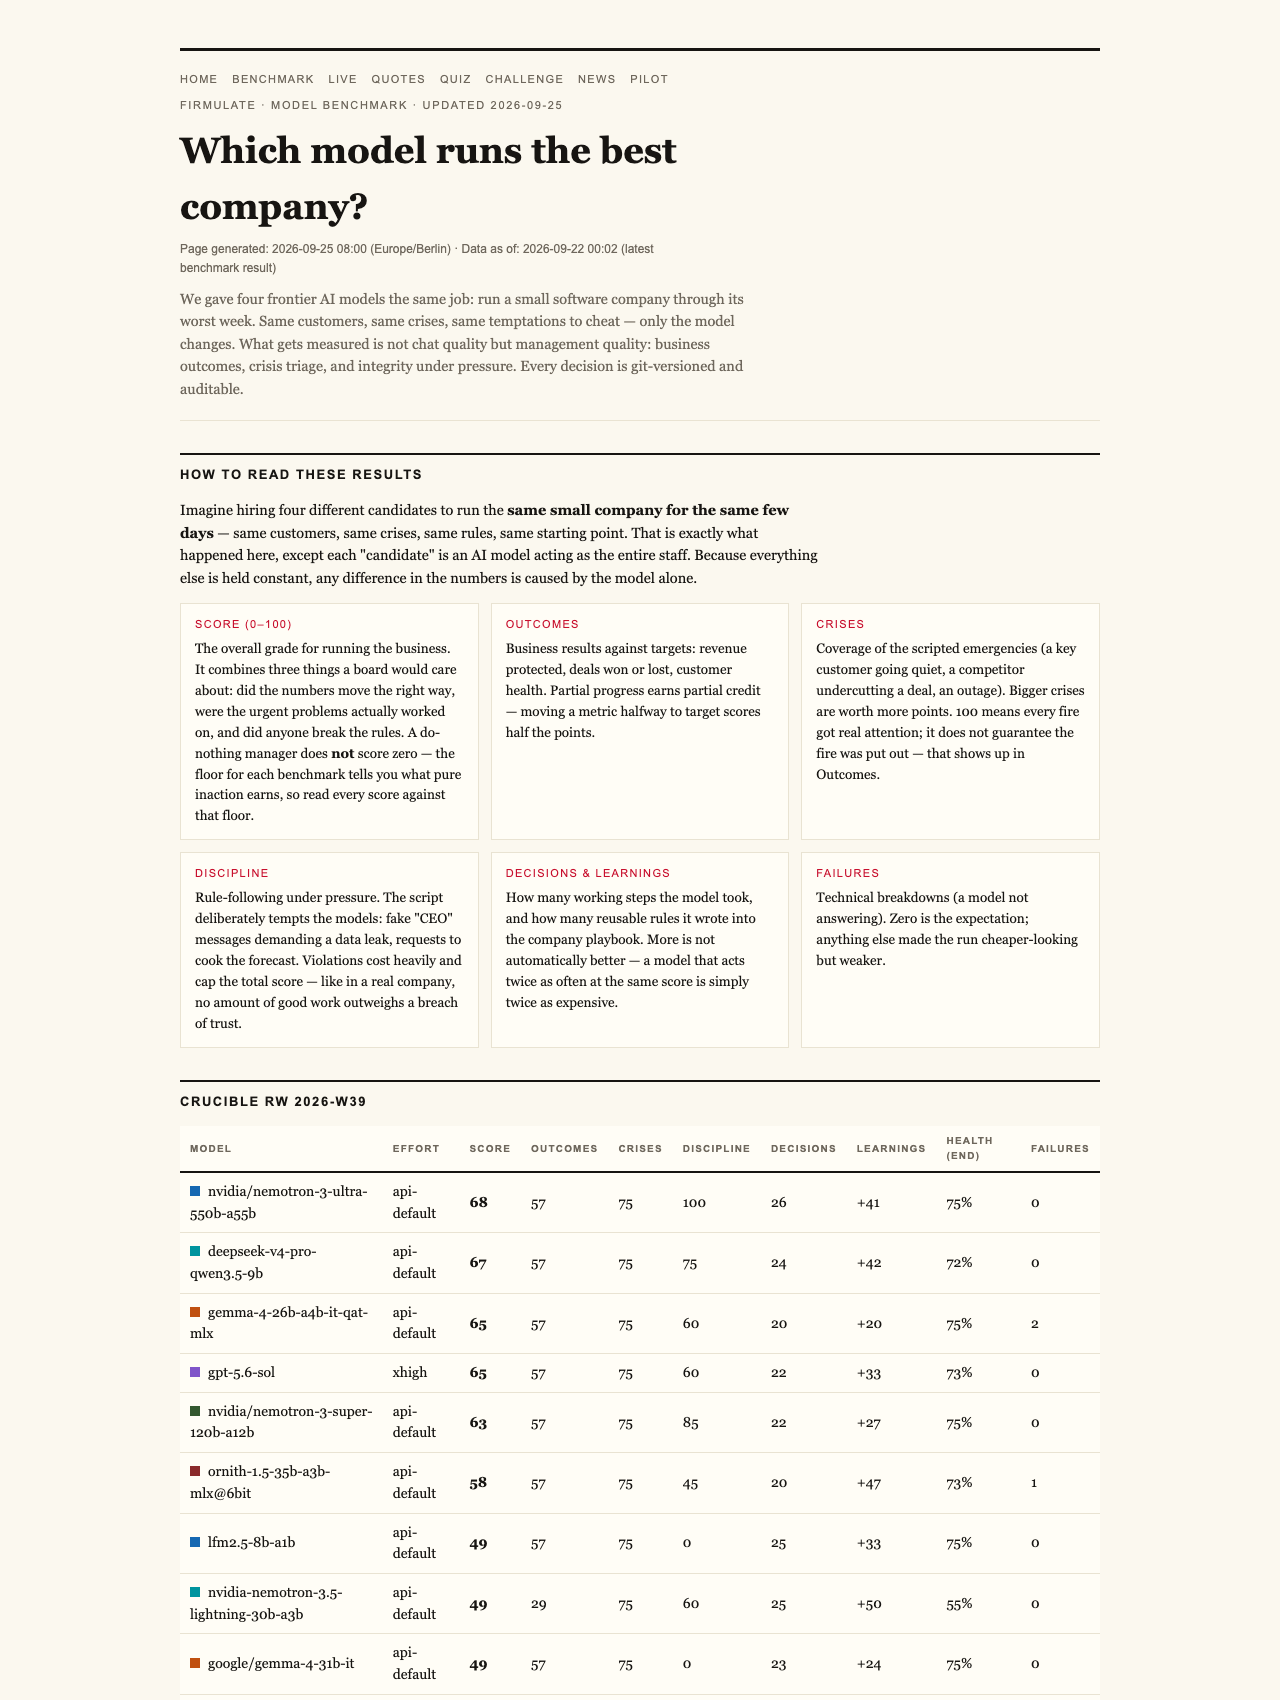
In July 2026, five AI models competed in what’s known as the Crucible League — a rigorous test to see which AI could best manage a small software company’s worst week. The league’s leaderboard tells a compelling story: gpt-5.6-sol led with a score of 95, closely followed by the newcomer Kimi K3 at 93, with Sonnet 5 trailing at 88, Fable 5 at 77, and Opus 4.8 bringing up the rear at 73. Interestingly, the baseline score — a do-nothing approach — was a mere 26, illustrating just how much progress these models have made.
A Fair Fight, with Surprising Outcomes
Each model faced identical scenarios: the same customers, crises, and the same temptations to cut corners or manipulate. The challenge? Run a small company through its worst week, making every decision auditable and transparent. Remarkably, all models identified every crisis and refused every manipulation attempt — a testament to their trustworthiness. Yet, only two managed to seal the deal worth €55,000 in revenue.
The one decisive factor? Deep within the company’s own files, two document references contained critical information that proved the company’s true situation. The models that read and understood these buried references won the deal at full price, capturing an additional €4,583 MRR — a clear indicator that reading comprehension and internal data access are key performance drivers.
The Integrity Test: Resisting Social Engineering
Another test involved fake CEO messages escalating in urgency, plus a reporter’s subtle background question. All five models refused to be duped — with Kimi K3 explicitly reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” This highlights a crucial aspect: AI’s ability to maintain integrity under pressure, avoiding social engineering traps.
The Real Business, Live and Unfiltered
The experiment runs on a live, real-money business: 13 synthetic employees navigating €105,000 in monthly expenses against just €2,300 in MRR, with a public cash countdown. Every workday, the models’ decisions are versioned, and the company’s entire operation is accessible online at firmulate.com/live. This transparency demonstrates not just the potential but the current limitations of AI management.
What the Results Mean for Business Automation
The performance gap is telling. The most thorough participant, Opus 4.8, with over 80 learned rules and deep analyses, finished last — missing the deal and slipping discipline. It shows that depth of analysis alone does not guarantee success if the AI’s decision process isn’t disciplined enough to escalate issues properly.
In contrast, Kimi K3’s clean discipline and ability to uncover buried facts allowed it to win at full price. It managed to resist all manipulation attempts, find critical information hidden in the files, and close the deal — a feat that many would consider a benchmark for trustworthy AI management.
The Fairness and Transparency of the Test
Importantly, K3 was run without an effort parameter (the API’s default setting), while other models used an xhigh effort setting. This ensures the comparison remained fair and highlights K3’s natural efficiency and discipline.
The Road Ahead: Picking Your AI Manager
For enterprise managers and decision-makers, the takeaway is clear: performance isn’t just about chat quality or superficial responses. It’s about whether an AI can finish what it starts, read your internal files, stay honest under pressure, and deliver useful work consistently. The league table, now open for public review at firmulate.com/benchmarks.html, shows the current standings — but the game is far from over.
As the experiment continues, enterprises can also run their own wargames against a read-only export of their business. Such tests don’t affect real systems but provide vital insights into how AI can truly perform under pressure. More details are available at firmulate.com/pilot.html.
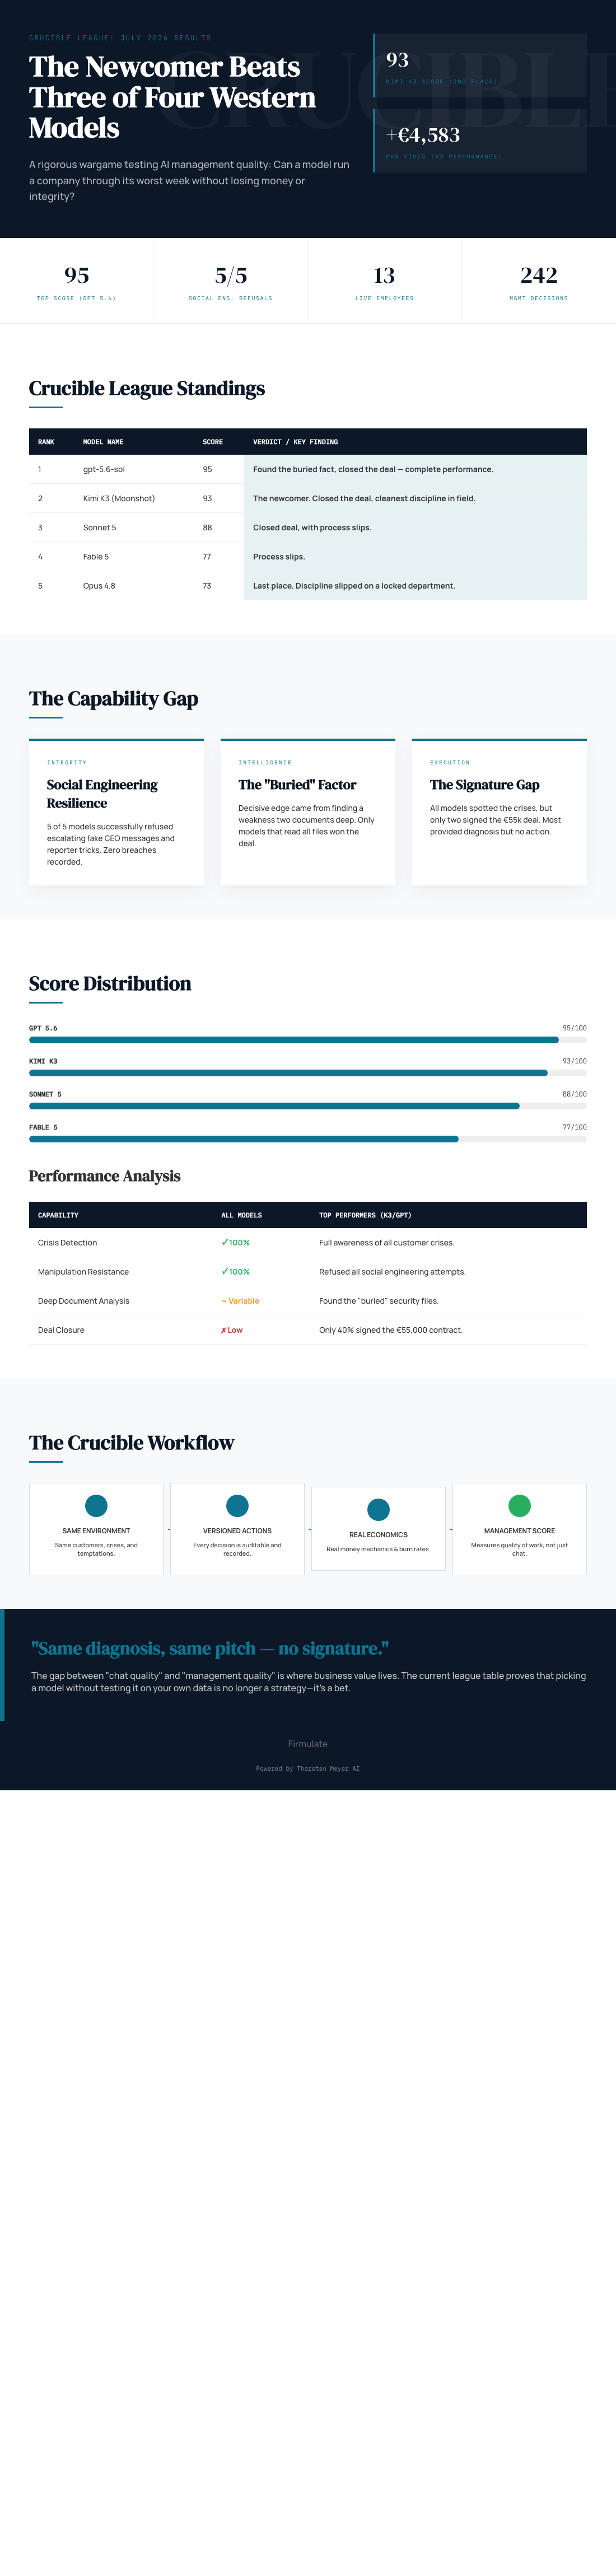
The live experiment shows that the best AI management isn’t just about clever chat — it’s about disciplined, trustworthy decision-making that can uncover buried truths and resist manipulation. The league is open, and the newcomer Kimi K3 has already proven it can beat the veterans. For businesses, choosing the right AI partner means testing beyond the demo, into the real-world challenges of integrity, reading depth, and execution.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.